

Blog · Oct 8, 2026
Introducing Nace Document Intelligence: The Perception Layer for AI Agents
Nace.AI
Nace Document Intelligence, the layer that reads your files
Generally available. Frontier parsing quality at a fraction of the cost.
Today, we're launching Nace Document Intelligence to help AI agents turn complex files into structured, grounded information. It's available now through the Nace Console and API.
Nace Document Intelligence (NDI) is our Perception Layer, while Drex is our Decision Layer. Use NDI on its own with your existing agents, or pair it with Drex for a single API from raw files to decisions. Together, they give agents a single API to understand files and make decisions on top of the information inside them.
NDI can parse, split, classify, extract, and ground 36 file types, including PDFs, scans, spreadsheets, emails, images, audio, and video. Every result stays connected to its source, whether that means a page and bounding box, spreadsheet cells, a text span, or a timestamp.
Agents are only as good as what they can read
Most real workflows don't start with clean text. They start with invoices, contracts, financial statements, spreadsheets, scans, emails, and mixed document packets.
Traditional OCR can recover text but often loses the structure around it. General-purpose frontier models can understand complex documents, but using them to process every page quickly becomes expensive.
NDI is built specifically for this layer, turning unstructured files into structured, grounded information that downstream agents can reliably use.
Five document processing tasks, one API
The Perception Layer gives builders five tools through the same Nace API.
Parse converts files into structured, layout-aware output while preserving tables and source locations. Split separates mixed packets into the documents inside them. Classify labels documents or pages using your taxonomy. Extract returns structured fields against a schema, including whether each value was found, missing, or ambiguous. Ground resolves information back to the exact place it came from.
Here is one field Extract read from an invoice, with the place it came from:
| Field | Extracted value | Source |
|---|---|---|
| Total due | $600.00 | Page 1, box (0.697, 0.569) to (0.911, 0.624) |
Box coordinates are fractions of the page, measured from its top left corner.
The result is not just an answer. It is an answer with the evidence behind it.
Frontier parsing quality at a fraction of the cost
Parsing is the first step in many document workflows, so we started our evaluation there. We compared NDI against leading document parsers and frontier models across public and internal parsing benchmarks, and measured what each one actually cost to run.
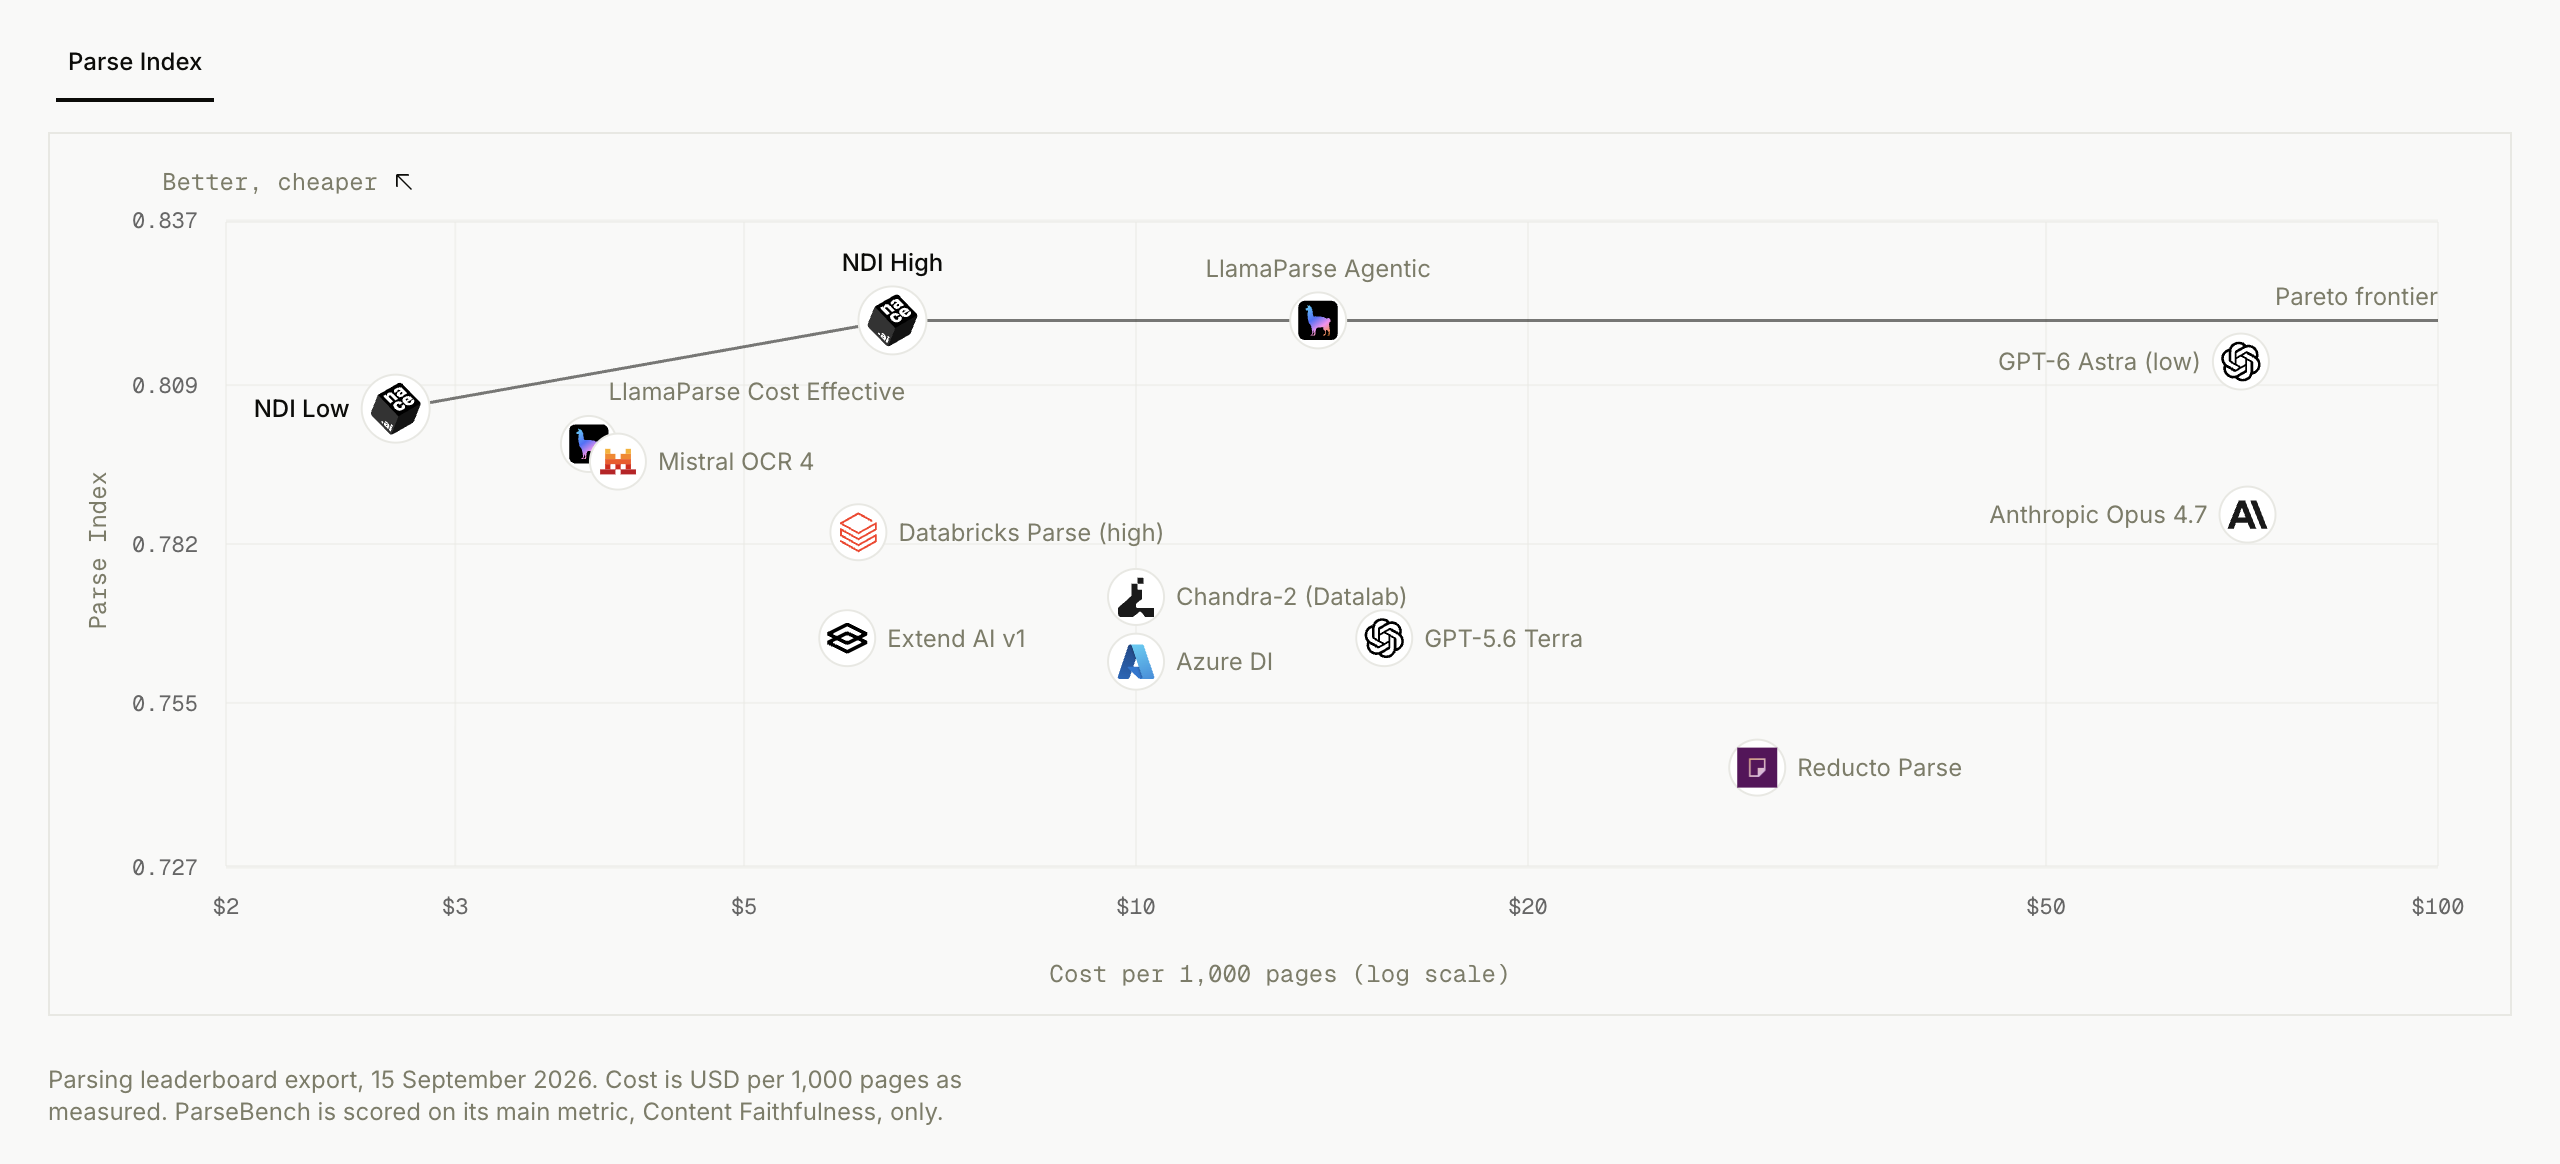
Nace DI High ties for the best score we measured (0.820) at less than half the cost of the only other model at that level, and roughly 10× cheaper than GPT-6 Astra. Nace DI Low is the cheapest option we tested, at $2.70 per 1,000 pages, and is outscored only by GPT-6 Astra among frontier models. Together, the two settings form the low-cost end of the Pareto frontier: no other system we tested is both cheaper and more accurate than either of them.
| Rank | Model | Parse Index | Cost / 1K pages |
|---|---|---|---|
| 1 | Nace DI High | 0.820 | $6.50 |
| 1 | LlamaParse Agentic | 0.820 | $13.80 |
| 3 | GPT-6 Astra (low) | 0.813 | $70.57 |
| 4 | Nace DI Low | 0.805 | $2.70 |
| 5 | LlamaParse Cost Effective | 0.799 | $3.80 |
| 6 | Mistral OCR 4 | 0.796 | $4.00 |
| 7 | Anthropic Opus 4.7 | 0.787 | $71.40 |
| 8 | Databricks Parse (high) | 0.784 | $6.12 |
| 9 | Chandra-2 (Datalab) | 0.773 | $10.00 |
| 10 | GPT-5.6 Terra | 0.766 | $15.51 |
| 10 | Extend AI v1 | 0.766 | $6.00 |
| 12 | Azure DI | 0.762 | $10.00 |
| 13 | Reducto Parse | 0.744 | $30.00 |
For document-heavy agents, these savings add up with every page. A roughly 10× reduction in parsing cost lowers the cost of the whole pipeline; the overall savings depend on how much of that pipeline's cost comes from parsing.
About the Parse Index
The Parse Index is the aggregate score reported in our September 2026 parsing leaderboard. Higher scores are better. The chart and table use the leaderboard's reported scores and measured costs; individual benchmark results are available on the Nace Document Intelligence page.
For ParseBench, we report Content Faithfulness, which measures text correctness and reading order.
Costs are USD per 1,000 pages as measured on our runs, using each provider's list pricing. Results are from our leaderboard evaluations as of September 2026.
Perception + Decision
NDI reads and structures the information inside your files. Drex takes that information and decides what to do next.
Both live in the same Console, use the same API key, and can be combined in a single workflow, giving builders a direct path from raw files to grounded decisions without stitching together separate systems.
Nace Document Intelligence is available now in the Nace Console.